
What is Agentbase
Agentbase is a one-stop backend and intelligent infrastructure platform for the engineering deployment of enterprise-grade AI-native applications and agents. Built on highly reliable application backend capabilities (authentication, relational and document databases, object storage, serverless cloud functions, messaging notifications, site hosting, and multimodal content moderation), the platform deeply integrates the LLM Gateway required by enterprise-grade agents, the unified AI Gateway, a rich-document hybrid retrieval knowledge base (Knowledge Base and domain Lexicon), long-term memory and skill self-evolution engine (Memory & Context Dreaming), the agent runtime workbench (Agent Runtime Workbench), and full-chain agent observability (AgentOps / Observability). This manual corresponds to Agentbase 2.10.0.
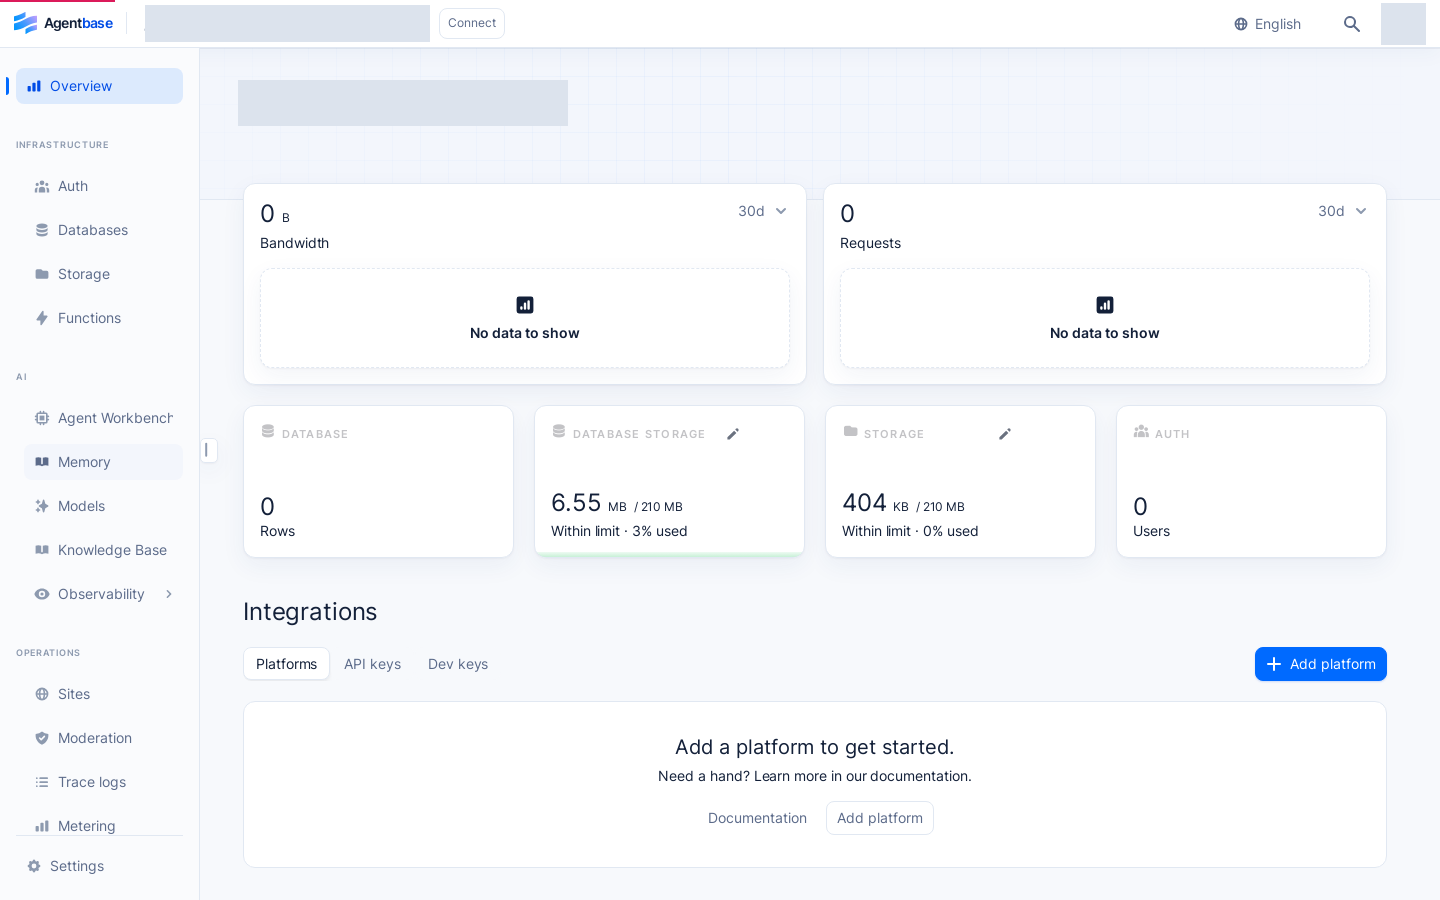
Interface reference: reuses previously registered historical screenshots; demo data may differ from the current project; no new screenshots were taken this time.
Feature Overview
When deploying intelligent customer service, knowledge assistants, development Copilots, and automated business agents in enterprises, engineering teams typically face the pain point of a split between "application backend infrastructure" and the "AI-native tech stack": on one hand, they must assemble user authentication, business ticket databases, multi-tenant permissions, object storage, and asynchronous task queues themselves; on the other hand, they must independently maintain model routing gateways, RAG vector parsing pipelines, synonym/stopword intervention lexicons, long- and short-term session memory, and OpenTelemetry trace evaluation systems. The authentication systems, tenant isolation boundaries, and metering/billing standards of multiple systems cannot be aligned, resulting in long development cycles and difficult production troubleshooting.
Agentbase converges traditional BaaS (Backend-as-a-Service) and Agent Infra under a unified account → organization (Organization) → project (Project) governance model. Taking a typical production scenario, "enterprise intelligent customer service and knowledge platform" (project ID: enterprise-ai-hub-210, belonging to organization: Agentbase 企业智能中台 69c6d1aa00062e6bb60), as an example, the enterprise can achieve the following full-stack closed loop within a single Project space:
Unified identity and business data hosting: manage customer service agent and end-customer identities via Auth; use the business database
enterprise_biz_dbbased on the OceanBaseShared V2model (such as the customer ticket tablecustomer_tickets) and bucketskb_enterprise_docsandagent_multimedia_bucketto host high-concurrency reads and writes of structured documents and unstructured multimedia.Multi-model routing and enterprise-grade safety guardrails: connect the Tongyi Qianwen DashScope production provider through the model gateway (
dashscope-prod, includingqwen-plus,qwen-turbo,text-embedding-v3,qwen3.7-text-rerank,qwen-vl-max), and configure logical model routinglm-enterprise-chat, safety guardrailsgp-enterprise-safety, and semantic caching policiescp-semantic-cachevia the AI gatewayprod-enterprise-ai-gateway(gw_7194685489feb1e169548619).Hybrid Retrieval RAG and Advanced Knowledge Compilation: In the knowledge base
kb_enterprise_support, ingest architecture whitepapers, customer service SOPs, and troubleshooting manuals; bind a synonym lexiconlex_enterprise_synonymsand a stopword lexiconlex_support_stopwords; and enable GraphRAG knowledge graph, RAPTOR hierarchical clustering summaries, and LLM Wiki compilation pages as needed.Long-Term Memory Extraction and Skill Distillation: Based on the
Shared V2engine, extract cross-session factual memory and user profiles for end users (such asuser_zhangwei_001anduser_lina_002), and asynchronously execute Context Dreaming context aggregation and Experience/Skill Distillation.Workbench Integration and Full-Chain Observability (AgentOps): In the agent workbench, bind the primary conversational model
qwen-plus, the enterprise knowledge base, and the intervention lexicon with one click for streaming debugging, while tracking the Span waterfall, Token cost, parsing chunk quality, and knowledge index quality score of every request in the AgentOps hub.
| Capability Domain | Core Modules | Core Business Problems Solved | Production-Grade Feature Highlights |
|---|---|---|---|
| Governance and Foundation | Account Center, organization management, project overview, limits and quotas, project settings | Multi-team development collaboration, multi-environment isolation, API credential authorization, and cost accounting | Three-level UTC daily aggregated metering, 15 client platform origin verification, and independent read-only ban switches for project database/storage |
| Application Backend (Build) | Auth, Databases, Storage, Functions, Sites, Messaging, Moderation | End-to-end application user system, relational/JSON data persistence, file hosting, event-driven computing, and compliance risk control | OceanBase Shared V2 high-performance table mode, Schema version rollback, SQL Proxy, Java 17 prebuilt JAR deployment, and multimodal synchronous/asynchronous content moderation |
| Models and Gateway (AI) | LLM Gateway (models), AI Gateway (unified AI gateway) | Multi-vendor credential custody, primary-backup failover, semantic cache acceleration, prompt guardrails, and quota throttling | One-click import of vendor catalogs such as DashScope, logical model routing, semantic cache hit analysis, and per-Key monthly Token budget control |
| Knowledge and Memory (AI) | Knowledge Base, Lexicon, Memory, PowerContext | Chunking and ingesting complex documents, proper noun retrieval correction, multi-hop knowledge reasoning, cross-session personalized memory, and skill evolution | Vector + full-text hybrid retrieval, hot synonym/stopword intervention, GraphRAG/RAPTOR/Wiki indexes, 4 types of publishable memory Pipelines, and image/PDF multimodal memory |
| Runtime and Operations (AgentOps) | Agent workbench (Agent Runtime), agent operations (Observability) | Rapid agent assembly verification, live conversation trace replay, low-score root cause diagnosis, and quantified RAG parsing and index quality evaluation | Project-level workbench configuration persistence, native OpenTelemetry integration, and built-in GraphRAG/RAPTOR/Wiki index quality assessment templates with independent model review |
Core Concepts and Architecture
Agentbase adopts a layered architecture with separation of the Console Plane and the Data Plane, and same-origin isolation of the traditional application backend and AI engines. All resources are strictly attached under the Account(账号) → Organization(组织) → Project(项目) three-level resource tree, with the project serving as the minimal complete boundary for data isolation, key authentication, service switches, table modes (JsonTable / Shared V2), and metering quotas.
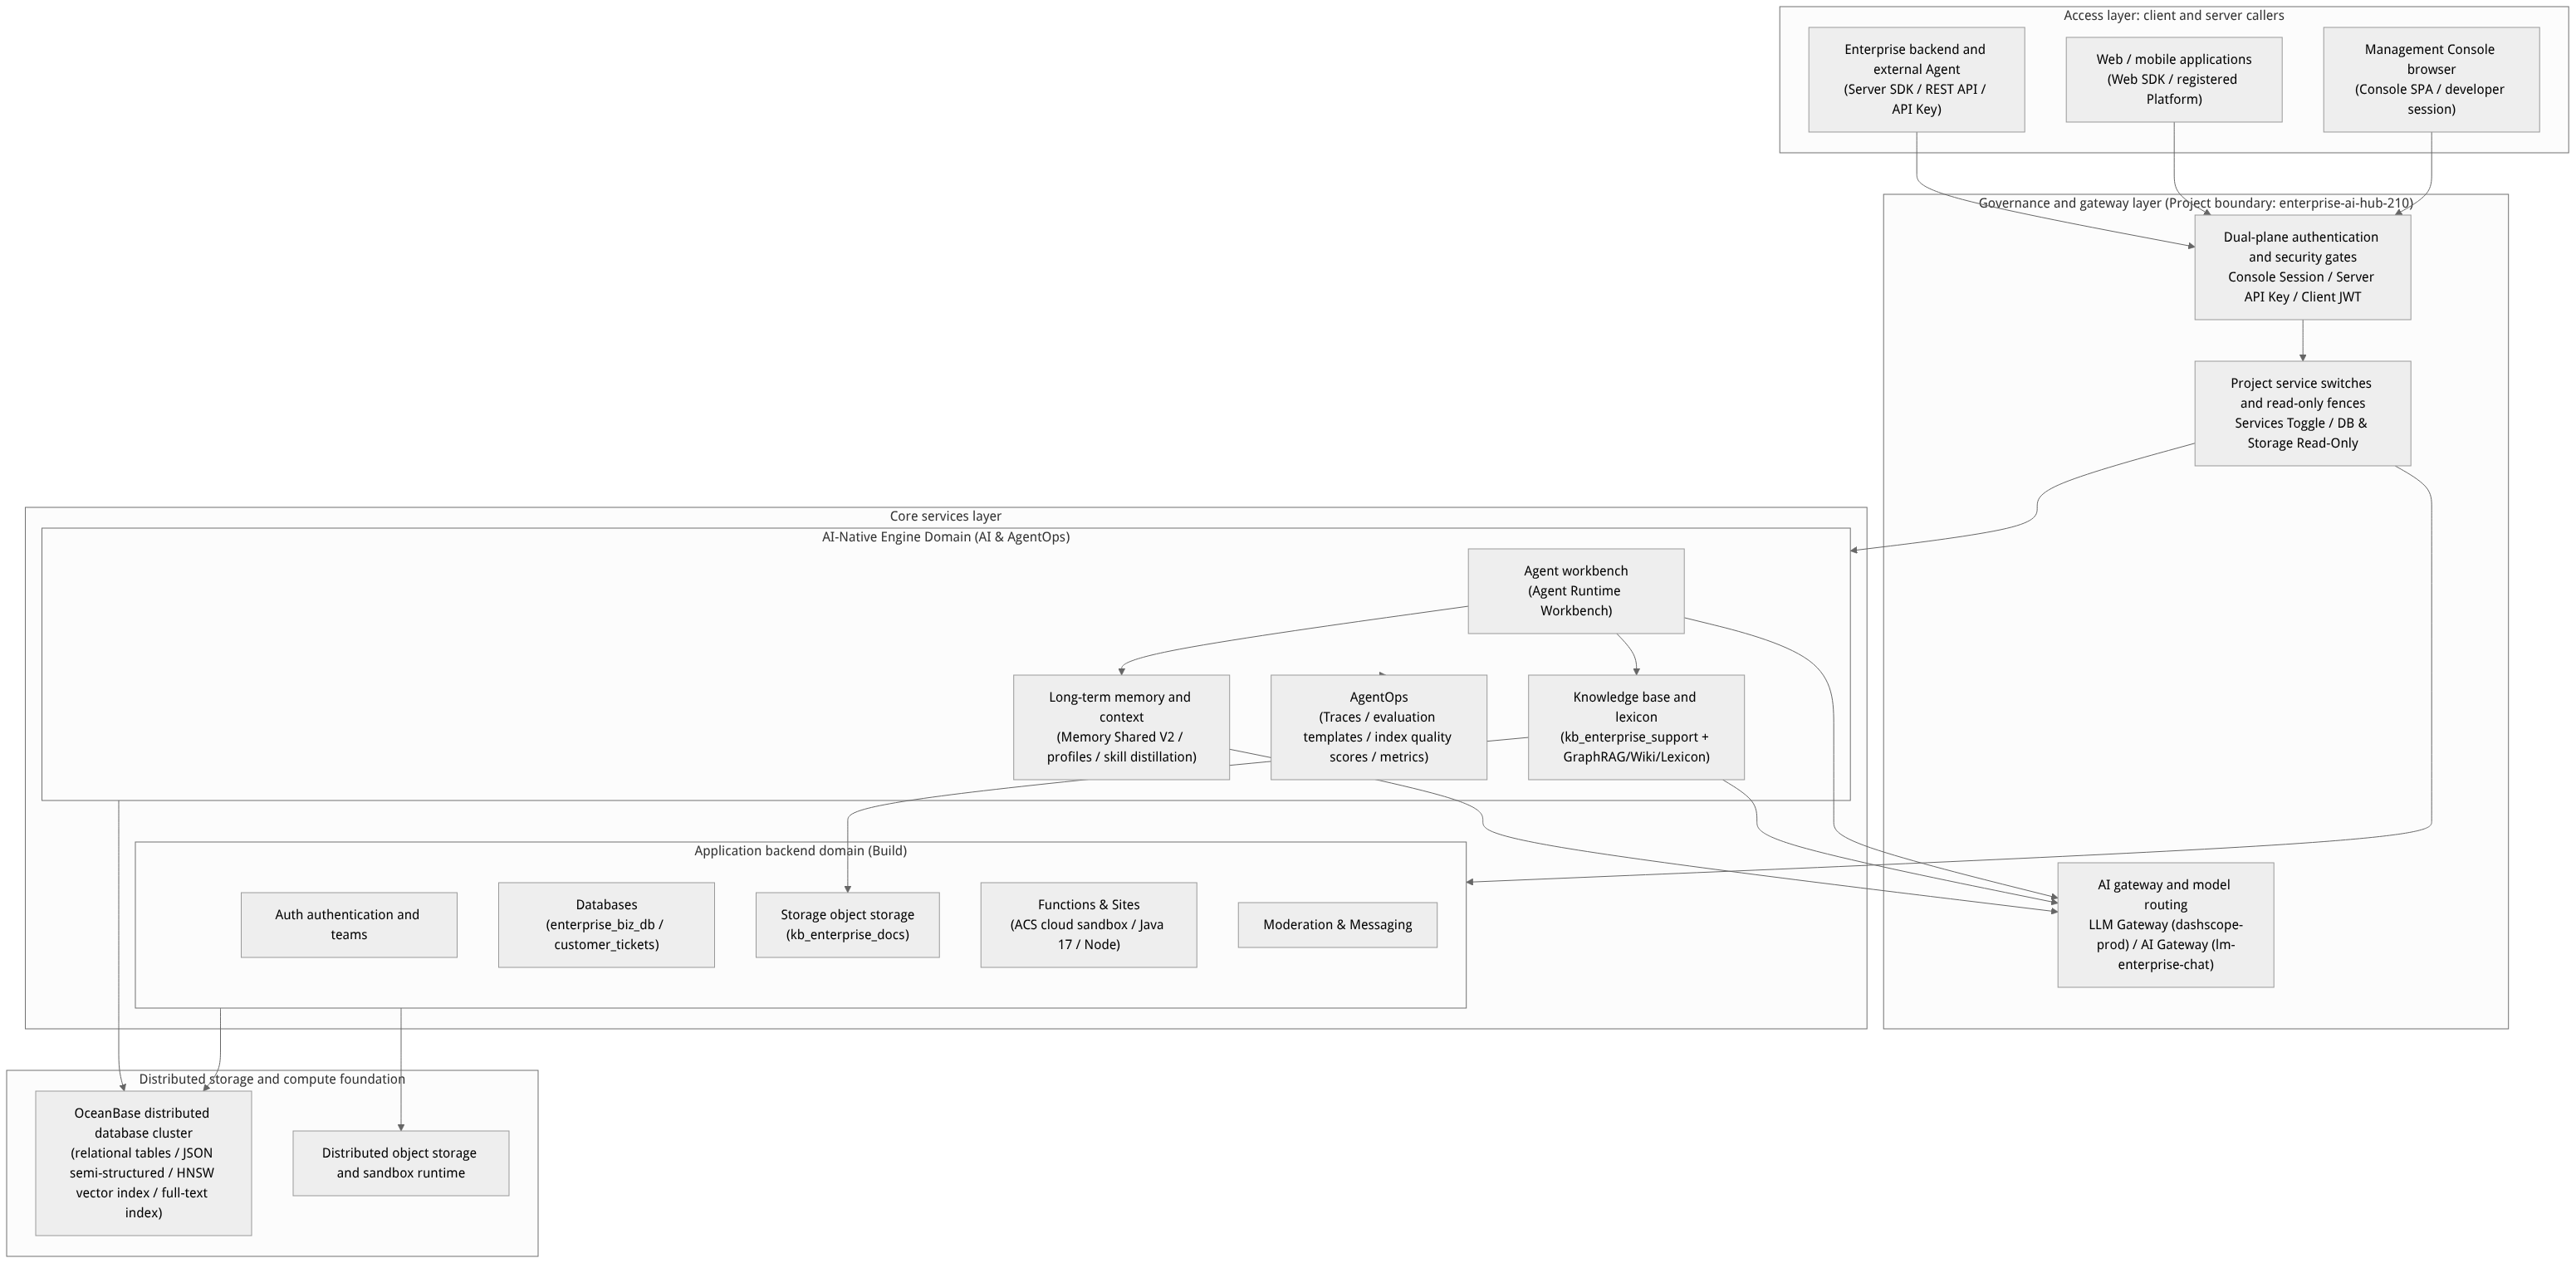
Flow diagram, not a runtime screenshot; read the relationships between steps or states along the arrows.
View the flow diagram in full size
Core Architecture Components Table
| Architecture Layer | Core Concept | Identifier and Example (Production Scenario) | Architecture Responsibilities and Engineering Constraints |
|---|---|---|---|
| Organization Layer (Organization) | Team and billing container | Agentbase 企业智能中台(69c6d1aa00062e6bb60) | Hosts multiple projects and centrally manages team member roles (owner, admin, developer, editor, billing, analyst), 30 daily aggregated usage, and inactive project cleanup. |
| Project Layer (Project) | Resource and security isolation boundary | 企业智能客服与知识中台(enterprise-ai-hub-210) | Binds to a physical region and the underlying table storage mode (e.g., Shared V2); databases, storage buckets, knowledge bases, memory spaces, and API Keys are fully isolated between projects. |
| Model Routing Layer | Vendors and logical gateway | dashscope-prod / prod-enterprise-ai-gateway | Centrally consolidates external LLM API Keys (stored masked, never echoed back), and internally provides a standard invocation surface for knowledge base chunk vectorization, memory extraction, online inference, and LLM-as-a-Judge evaluation. |
| Knowledge and Memory Layer | Structurally enhanced context | kb_enterprise_support / lex_enterprise_synonyms / Memory | Combines raw documents in storage buckets, vector indexes, lexicon synonym expansion, and user long-term factual memory to assemble high-recall, low-hallucination dynamic Prompt contexts for agents. |
| Observability and Evaluation Layer | AgentOps closed-loop quality governance | Traces / Observations / Evaluations | Automatically collects or receives agent execution traces via OTLP, providing quantified scoring and root cause analysis from chunk parsing quality and GraphRAG/Wiki index artifact quality to end-to-end response quality. |
Roles, Entry Points, and Relationships
In daily development and operations, team members in different roles collaborate to deliver applications through different Console views. Understanding Console role permissions, service switches, and the boundary between the Console Plane and the Data Plane is a prerequisite for using Agentbase securely.
1. Organization Roles and Operation Permission Matrix
| Organization Role | Typical Position | Application Backend and AI Resource Write Permission | API Key / Credential Management | Organization Settings and Member Governance | Usage and Observability Visibility |
|---|---|---|---|---|---|
| Owner | Platform architect / technical lead | Full read/write (including column deletion, table mode conversion, project deletion) | Create, edit, view full Secrets, revoke | Create/delete organizations, invite/remove members, clean up inactive projects | Full three-level view of account, organization, and project |
| Admin | Development lead / operations lead | Full read/write (excluding destructive switches restricted to Owner) | Create, edit, view authorized Secrets, revoke | Modify organization settings and invite members (cannot delete organization) | Full organization and project view |
| Developer | Backend engineer / AI algorithm engineer | Read/write databases, storage, functions, knowledge bases, memory, gateway, and evaluations | Create and manage project API Keys / Dev Keys | Read-only view of member list | Full organization and project view |
| Editor | Knowledge operations / Prompt engineer | Maintain table data, knowledge base documents, lexicon entries, and evaluation datasets | Use within authorized scope | Read-only view of member list | Project-level business and observability view |
| Billing | Finance and procurement specialist | Read-only (cannot modify business configuration or trigger builds) | Cannot create or view Secrets | Manage bills, invoices, and subscription plans | Organization and project usage metering view |
| Analyst | Data analyst / quality inspector | Read-only (cannot modify business resources) | Cannot create or view Secrets | Read-only view | Observation traces, evaluation reports, and usage statistics |
2. Product Capability Boundaries and Four Core Principles
Principle One: Deployment-level capabilities take effect separately from project switches. Advanced knowledge base indexing (GraphRAG / RAPTOR / Wiki), the unified AI gateway, site hosting (
_APP_SITES_ENABLED), and long-term memory are governed by underlying deployment environment variables and compute components. If a capability is not deployed on the current instance, the API will stably return HTTP412 Precondition Failedrather than pretending it is "disabled within the project"; version upgrades themselves do not automatically enable deployment-level switches that are disabled by default.Principle Two: Console visibility (Console routes) does not mean the Data Plane is ready. Showing a module entry in the left sidebar only means the Console frontend route and role permissions allow it; whether actual business requests succeed depends on the project Settings → Services switches, the resource's own
enabled/activestatus, the connectivity of the bound model Provider, and the storage mode (e.g., Memory strictly requires the project to be in theShared V2table mode).Principle Three: Developer identities (Console Account) and end-user identities (Project Auth User) are strictly physically isolated. The account used to log in to
/console/loginis for managing organization and project infrastructure; users under the project Auth module (such asuser_zhangwei_001) are end customers or customer service staff of the enterprise business system. The two sets of session cookies, JWTs, and permission selectors are entirely independent and must never be mixed.Principle Four: Protocol versions and SDK response formats are negotiated precisely. The running version of the target instance can be verified in real time via the public unauthenticated endpoint
GET /v1/health/version(the current stable version returns{"version":"2.10.0"}). Agentbase's official in-house SDKs (such asagentbase-node-sdk@2.10.0,agentbase-web-sdk@2.10.0, andagentbase-console-sdk@2.10.0) negotiate the 2.10.0 full response structure via the request headersX-AppBase-SDK: trueandX-Appwrite-Response-Format: 2.10.0, while native Appwrite-compatible clients are protected by an independent version cap (default1.9.0).
Feature Details and Operation Guide
This section explains, from the perspective of an enterprise team newly onboarding, how to use the Console to verify the platform version, gain a global understanding of the project, and follow the standard evolution path from basic services to AI modules.
1. Verify the Instance Service Version and Console Entry Points
Before starting project configuration, it is recommended to first confirm the server version of the current environment and log in to the Console:
Run the public health check endpoint in a terminal (no API Key required):
curl -fsSL https://appbuild.oceanbase.com/v1/health/versionThe expected response is HTTP
200 OKwith the JSON payload{"version":"2.10.0"}.Open the Console address
https://appbuild.oceanbase.com/console/in a browser, log in with the enterprise developer account and complete MFA secondary verification, switch to the target organizationAgentbase 企业智能中台(ID:69c6d1aa00062e6bb60) in the top navigation bar, and click to enter project企业智能客服与知识中台(ID:enterprise-ai-hub-210).After entering the project, the Overview page is displayed by default (as shown in Figure 1); the top shows real-time connection count, request trends, database read/write throughput, and storage usage summaries; the Integrations area at the bottom centrally manages registered client platforms (Platforms), server production keys (API keys), and development/debug keys (Dev keys).
2. Console Left Sidebar Sections and the Standard Build Flow
The left navigation bar of the Agentbase project Console is divided into three core areas according to the development evolution lifecycle; teams are advised to build enterprise intelligent applications layer by layer in the following order:
| Build Stage | Sidebar Entry Name | Console Route Suffix | Key Configuration Actions and Outputs (using enterprise-ai-hub-210 as an example) |
|---|---|---|---|
| Stage One: Project Foundation and Security Baseline | Overview / Settings | /overview · /settings | Confirm the project table mode is OceanBase Shared V2; enable services such as AI Gateway, Knowledge Bases, and Memory in Services; create a standard_ API Key following the least-privilege principle. |
| Phase Two: Application Backend Build (Build) | Auth / Databases / Storage / Functions / Moderation | /auth · /databases · /storage · /functions · /moderation | Configure end-user login methods; create the business database enterprise_biz_db and the ticket table customer_tickets (with entries such as ticket TK-20261022-001); create the storage bucket kb_enterprise_docs and upload policy documents; enable multimodal content moderation on the write path. |
| Phase Three: Model Gateway and Routing Governance (AI) | Models / AI Gateway | /llm-gateway · /ai-gateway | On the Models page, add dashscope-prod from the preset catalog (importing qwen-plus, text-embedding-v3, qwen3.7-text-rerank, qwen-vl-max); on the AI Gateway page, create prod-enterprise-ai-gateway and bind the logical model lm-enterprise-chat, safety guardrail gp-enterprise-safety, and semantic cache cp-semantic-cache. |
| Phase Four: Knowledge Engineering and Long-Term Memory (AI) | Knowledge Base / Lexicon / Memory / Context | /knowledge-base · /memory · /powercontext | Create the synonym dictionary lex_enterprise_synonyms and the stopword dictionary lex_support_stopwords; create the knowledge base kb_enterprise_support, upload 4 core enterprise Markdown documents, and build GraphRAG, RAPTOR, and a compiled Wiki of 10 pages; initialize the Shared V2 Memory service, configuring the four types of Memory Pipelines and experience and skill distillation. |
| Phase Five: Agent Integration Testing and AgentOps | Agent Workbench / AgentOps / Trace logs | /agent-runtime · /observability · /logs | In the Agent Workbench, bind qwen-plus and kb_enterprise_support for multi-turn conversation testing; in AgentOps, view the Trace waterfall and run knowledge base parsing evaluation and knowledge index quality evaluation tasks. |
3. 2.10.0 Core Feature Panorama Checklist
To help architects upgrading from earlier versions or evaluating the platform for the first time quickly grasp the current baseline capabilities, the table below summarizes the key production capabilities of Agentbase 2.10.0 and the corresponding verification methods:
| Feature Name | Module | Core Configuration Item or Interface Identifier | Console Verification Result |
|---|---|---|---|
| Standalone Knowledge Index Quality Evaluation | AgentOps → Evaluation | Built-in templates: GraphRAG / LLM Wiki / RAPTOR Index Quality; by default, 30 items are sampled per capability layer | to generate 0~1 capability-level quality scores; after independent model review, supports drilling down by kind=index to view per-item rule and model scoring details |
| Document Hierarchy Tags and Sub-Product Filtering | Knowledge Base → Documents / Retrieval Testing | documentTag ({subProductId}_{sectionCode}_{fileKey}) and a standalone subProductId field | The document list supports tag tree/flat view switching, and single-library and cross-library retrieval support precisely narrowing the retrieval scope by subProductId and metadataFilter |
| Intervention Lexicon Closed Loop | Knowledge Base → Lexicon | Synonym dictionary (bidirectional equivalence/unidirectional expansion) and stopword dictionary | Once bound to a knowledge base or the Agent Workbench, hybrid retrieval automatically performs business jargon expansion and removal of high-frequency noise words |
| Four Types of Memory Pipelines and Skill Secondary Confirmation | Memory → Configuration / Experience & Skills | Four types of Pipelines: Memory, Profile, Experience & Skills, and Forgetting; evolution.requireConfirmation | supports Pipeline draft saving, real-sample validation, publishing, and rollback; skill distillation supports candidate version Diff comparison, manual editing, and approval/rollback |
| Java 17 Prebuilt JAR Function Deployment | Functions → Deployment | Runtime java-17.0 + artifactMode=java-jar (manifest declares Main-Class) | No need to upload a source archive for recompilation; upload a prebuilt JAR within the valid size limit (default 100 MB, also subject to plan limits); wait for the deployment to become ready, then confirm activation and execution results |
| Project Database and Storage Standalone Read-Only Fence | Limits and Quotas (Platform Governance) | databaseReadOnly / storageReadOnly | While enabled, writes to the corresponding domain are rejected (returning project_database_read_only or project_storage_read_only), guaranteeing zero dirty writes during migration and fault isolation periods |
2.10.0 Notable Capabilities
Knowledge Base Positioning and Filtering: Documents can be precisely located using
documentTagandsubProductId; single-library / cross-library retrieval, document lists, and Graph / Wiki conflict lists support filtering by tag or sub-product. Hierarchy tags remain for directory organization; the two serve different purposes. See Documents and Ingestion and Retrieval Testing.Knowledge Index Quality Evaluation: Observability can separately evaluate the index artifacts of GraphRAG, RAPTOR, and LLM Wiki; corresponding index results must already exist before evaluation. See Evaluation and Scoring.
Versioned Knowledge Base: You can create a working copy from a READY version, seal it, publish it, and retain limited rollback targets. See Version Management.
FAQ and Troubleshooting
Q1: Why can't I see "AI Gateway", "Messaging", or "Sites" entries in the Console's left navigation bar?
Cause and troubleshooting steps:
AI Gateway: The project-level service switch is disabled by default. Have a member with project write permission (
owner/admin/developer/editor) go to Settings → Overview → Services, find AI Gateway (Unified AI Gateway), and toggle it to enabled; after refreshing, the AI Gateway entry will appear in the sidebar.Messaging: In the current version, this navigation item is hidden from the sidebar by default, but the underlying service is fully available. You can access it directly in the browser via
/console/project-{region}-{project}/messaging(for example/console/project-default-enterprise-ai-hub-210/messaging), or jump straight to it using the shortcut command center at the top of the Console.Sites: Controlled jointly by the instance-level deployment environment variable
_APP_SITES_ENABLEDand an email whitelist. If the variable is not enabled on the current private or pre-production instance, the sidebar automatically hides the Sites entry.
Q2: Why does calling a knowledge base advanced index or Memory interface return HTTP 412 Precondition Failed?
Cause and troubleshooting steps: In Agentbase, HTTP 412 explicitly means a Prerequisite or deployment-level Capability is not satisfied, rather than an ordinary parameter error (400) or insufficient permission (401/403). Common triggering scenarios include:
Project table schema mismatch: For example, attempting to initialize the Memory service in a project using the legacy
JsonTabletable schema (Memory strictly requires the project to use the OceanBaseShared V2table schema). Please check the project's Settings → Overview → Project Table Schema.Required model route not bound: For example, before enabling knowledge base GraphRAG/Wiki building or triggering asynchronous Memory extraction, no usable Chat and Embedding models have been configured in Models (LLM Gateway).
Corresponding optional component not deployed on the instance: Contact the platform infrastructure administrator to verify whether the corresponding Worker queues and index services are enabled.
Q3: Why does a server-side script calling an API with an API Key return 401 general_unauthorized_scope?
Cause and troubleshooting steps: Agentbase project API Keys strictly follow the Least Privilege principle. If, when creating an API Key, you do not check the Scope the target interface belongs to (for example, calling user queries without checking users.read, or calling knowledge base retrieval without checking the knowledge-base-related Scope), the server will intercept the request directly and return general_unauthorized_scope. Go to the project's Overview → Integrations → API keys, open the corresponding Key's detail page, complete the required permissions in the Scopes collapsible panel, and save; it takes effect immediately without changing the Key Secret.
Q4: After turning off a Service switch in project settings, will existing data be wiped? Can backend services still access it?
Cause and troubleshooting steps: No data is deleted, and server-side API Key access is unaffected. The switches in the project's Settings → Services only control the reachability of the client access surface (Client SDK / direct access from browsers and mobile clients carrying a user Session). After a service is turned off, direct requests from frontend applications are rejected, but calls initiated by backend microservices carrying a valid Server API Key still execute normally, and the underlying database tables, storage bucket files, and knowledge base indexes remain fully preserved.
Related Documentation
For easy reference to all site features, the following is a direct index of all chapters in this manual (zh-CN):
Introduction and Global Reference
Accounts, Organizations, and Project Governance
Authentication and User Management (Auth)
Databases and Data Governance (Databases)
Application Backend Services (Storage / Functions / Sites / Messaging / Moderation)
Model Gateway and Unified AI Gateway (Models & AI Gateway)
Knowledge Base and Lexicon Engineering (Knowledge Base & Lexicon)
Long-Term Memory and Context Engineering (Memory & Context)
Agent Workbench (Agent Runtime)
Model, prompt, context compression, and lexicon interception configuration
Multi-turn conversations (Threads), async runs (Runs), and resumable SSE event streams
Mounting enterprise knowledge base retrieval, long-term memory, and PowerContext integration
Business tool gateway (AI Gateway / MCP), client tools, and skill packages (Skills)
Agent observability and evaluation (AgentOps / Observability)