
Knowledge Distillation of Experiences and Skills
Feature overview and core scenarios
In enterprise-grade agent production systems, traditional declarative memory (e.g., single facts fact and user preferences preference) can only answer “who the user is and what the system's current configuration is”, but cannot answer “when encountering a certain type of complex production failure, which methodology and steps should be followed to invoke tools and resolve the problem”. As customer support and operations agents handle hundreds to thousands of multi-turn support ticket conversations and tool execution trajectories every day, if successful troubleshooting operation trajectories cannot be consolidated into procedural knowledge, the agent must still trial-and-error from scratch the next time it encounters a similar failure.
Agentbase Memory (v2.10.0) provides native Experiences and Skills knowledge distillation capability. Through an orchestrable seven-step knowledge distillation pipeline (distillation Pipeline), the system drives the DashScope conversational reasoning model (qwen-plus under dashscope-prod) and the 1024-dimension dense vector model (text-embedding-v3) to automatically transform raw session messages (messages) and tool invocation event trajectories (toolEvents) into two types of highly structured procedural knowledge assets:
Troubleshooting Experience: records “under a specific business scenario (
scenario), what specific problem (problem) was encountered, what key actions (action) were taken, what results (outcome) were produced, and the core pitfall-avoidance lessons (lesson) distilled”;Standardized Skill: consolidates “when certain trigger conditions (
triggerConditions) are met, which ordered steps (steps[]) should be followed, what parameters (parameters) should be passed, which tools or SQL commands executed, and how to verify the results (Verification)”.
In the example project 企业智能客服与知识中台 (project ID: enterprise-ai-hub-210, based on the OceanBase Shared V2 storage mode) of Agentbase 企业智能中台 (organization ID: 69c6d1aa00062e6bb60), the operations team submitted the conversations and tool trajectories of VIP architects user_zhangwei_001 and frontline engineers user_lina_002 handling real support tickets such as OceanBase 向量内存不足 (-4013) and AI 网关 429 限流自动故障转移 for distillation (e.g., production distillation tasks dst_3e5b09f456c5d5c332507ec1dbe3eb6d and dst_adc2cfda21c940fb5d5e4a3263ae56f9), achieving automatic cross-session, cross-user reuse of troubleshooting wisdom.
Core Concepts and Architecture
The knowledge distillation engine of Agentbase Memory chains evidence reception, skill extraction and merging, experience extraction and association, safety and quality validation, and storage projection through a seven-step standard pipeline (7-Step Distillation Pipeline), as shown in the following figure:
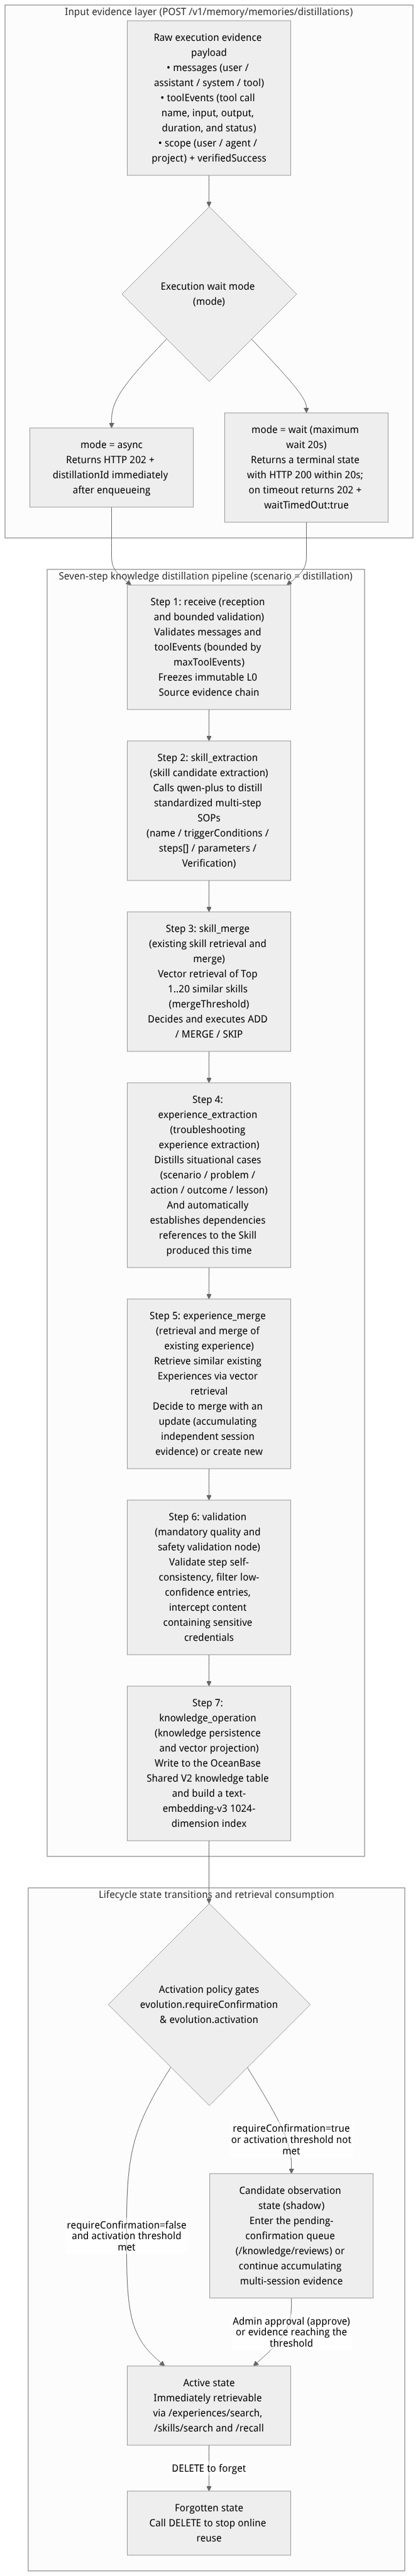
Flow diagram, not a runtime screenshot; read the relationships between steps or states along the arrows.
View the flow diagram in full size
1. In-depth comparison of the Experience vs Skill structured models
Although Experience and Skill both belong to the L1 procedural knowledge layer (sharing the knowledgeId naming scheme and immutable revision versions revisionId), they have clearly distinct responsibilities in cognitive positioning, structured Schema, and consumption methods:
| Comparison dimension | Troubleshooting Experience (Experience) | Standardized Skill (Skill) |
|---|---|---|
| Core cognitive positioning | Contextualized cases and pitfall-avoidance guides (Case-Based Reasoning): answers “under what business background and failure symptoms, why a certain approach worked or failed, and what lessons were learned”. | Executable Standard Operating Procedure (SOP): answers “when a certain condition is triggered, what to check in step one, which tool to invoke in step two, how to fill in parameters, and how to verify recovery”. |
| Structured core fields | - title: Experience title (e.g., "OceanBase Shared V2 向量索引构建内存不足 (-4013) 应急处置经验")- scenario: Business and technical context of the situation- problem: Specific error phenomena, symptoms, and root cause identification- action: Troubleshooting or tuning measures actually taken- outcome: Business recovery outcome and quantified metrics after resolution- lesson: Transferable core insights and pitfall warnings (insights / lesson)- tags: Domain classification tag array- confidence: Model-assessed confidence (0.0 ~ 1.0)- scope: Scope of ownership (user / agent / project) | - name: Skill standard name (e.g., "ob_vector_memory_limit_expansion_sop")- description: Overview of skill objectives and applicable boundaries- triggerConditions: Explicit prerequisites or error-code matching rules that trigger the skill (triggers)- steps[]: Ordered array of execution steps (each step includes a sequence number, action instruction, expected tool call, and decision branches)- parameters: Parameter templates and variable constraints required by the steps (inputs)- Verification: Acceptance check criteria after execution and rollback contingency plans- dependencies: List of dependent Prerequisite skills, tools, or permissions- scope: Scope of ownership (user / agent / project) |
| Cross-references | An Experience can be associated with and reference the Skill produced in this run or previously (when a dependent Skill has not yet been approved and activated, skill_dependency_not_approved protection is triggered). | Skill In the distillation pipeline, executes before Experience extraction (Step 2 & 3), so that the subsequent Experience (Step 4) can directly reference the already standardized skill identifiers. |
| Prompt injection timing | Injected when the agent performs root cause analysis, solution selection, or answers complex queries, providing references from similar historical cases. | Injected when the agent plans tool calls (Tool Planning) or executes automated operations SOPs, guiding precise multi-step operations. |
2. Node-by-node breakdown of the seven-step knowledge distillation pipeline (distillation Pipeline)
In Memory → Configuration → Experiences & Skills Pipeline, each distillation pipeline always consists of the following 7 sequential nodes:
| Step number | Node identifier (step) | Required | Core processing logic, model invocation, and tunable parameters |
|---|---|---|---|
| Step 1 | receive | Required | Receive and perform bounded evidence validation: Validates the input messages conversation turns and toolEvents tool execution traces (using maxToolEvents to limit the maximum number of tool events per run, preventing excessively long loop logs from blowing up the context), and freezes an immutable L0 raw evidence record in the OceanBase sources table. |
| Step 2 | skill_extraction | Optional (at least one of Step 4 and this step must be enabled) | Extract reusable SOP skill candidates: Invokes qwen-plus (structuredOutputMode: "tool_call") to analyze the successful tool call sequences in the conversation and toolEvents, distilling candidate skills containing name, triggerConditions, steps[], parameters, and Verification. Supports custom skillDistillationPrompt. |
| Step 3 | skill_merge | Linked with Step 2 | Retrieve similar existing skills and decide on merging: Uses text-embedding-v3 (1024-dimensional) to retrieve the Top maxCandidates (value 1~20) existing skills within the same governance scope, and combines the cosine similarity threshold mergeThreshold (value (0, 1]) with skillMergePrompt to let the model decide: create a new independent skill (ADD), merge and supplement into an existing skill and generate a new revised version (MERGE), or skip duplicates (SKIP). |
| Step 4 | experience_extraction | Optional (at least one of Step 2 and this step must be enabled) | Extract troubleshooting experiences and associate skill references: Invokes qwen-plus to distill contextual cases from the full task picture (scenario, problem, action, outcome, lesson), and automatically binds the relevant skills produced by Step 2/3 as knowledge references. Supports custom experienceDistillationPrompt. |
| Step 5 | experience_merge | Linked with Step 4 | Retrieve similar existing experiences and decide on merging: Retrieves the Top maxCandidates (1~20) similar existing experiences, and performs cross-session merging based on mergeThreshold and experienceMergePrompt (automatically accumulating evidence from independent session sources sourceIds, helping reach the minIndependentSessionsForAgent activation threshold) or creates a new entry. |
| Step 6 | validation | Required | Quality and safety gate validation: An independently enforced validation node (supports customization via evolutionValidationPrompt). Responsible for checking the step logical consistency of candidate knowledge, evidence support, and confidence score (confidence), and proactively filtering low-confidence entries or intercepting non-compliant candidates containing unredacted keys/passwords. |
| Step 7 | knowledge_operation | Required | Knowledge persistence and status routing: Within a single transaction, persists the knowledge master record, immutable version snapshots (Revision), L0 source associations, and 1024-dimensional vector projections. Depending on the project evolution.requireConfirmation and evolution.activation policies, decides whether to set directly to active or route into the shadow pending confirmation queue. |
Feature Entrypoints and Permission Matrix
The Console entry point is located at: Project enterprise-ai-hub-210 → Memory → Experiences & Skills tab (route: /console/project-{region}-enterprise-ai-hub-210/memory?tab=evolution), with the accompanying pipeline configuration located at Memory → Configuration → Experiences & Skills Pipeline.
| Functional action | Console UI entry point | REST API endpoint | Server SDK method (agentbase-node-sdk@2.10.0) | Required RBAC / API Key Scope | Cross-module dependent association |
|---|---|---|---|---|---|
| Submit a knowledge distillation task | Experiences & Skills → Manual distillation → Submit | POST /v1/memory/memories/distillations | memory.submitDistillation | memories.write | Calls Model routing (qwen-plus / text-embedding-v3) and the Configuration Center |
| Query the distillation task list and details | Experiences & Skills → Distillation task list | GET /v1/memory/memories/distillations, GET .../{distillationId} | memory.listDistillations / memory.getDistillation | memories.read | Associated with Memory audit and Memory tracing |
| Replay failed/historical distillation tasks | At the end of a distillation task row Replay | POST /v1/memory/memories/distillations/{distillationId}/replay | memory.replayDistillation | memories.write | Re-executes the distillation pipeline based on frozen raw L0 sources |
| List and semantically search Experiences | Experiences & Skills → Experiences list and search box | GET /v1/memory/memories/experiences, POST .../experiences/search | memory.listExperiences / memory.searchExperiences | memories.read | Provides contextual experiences for the agent workbench and recall |
| List and semantically search Skills | Experiences & Skills → Skills list and search box | GET /v1/memory/memories/skills, POST .../skills/search | memory.listSkills / memory.searchSkills | memories.read | Provides multi-step SOPs for the agent workbench and recall |
| Trace the L0 raw source of an experience/skill | Expand experience or skill details → Source evidence | GET /v1/memory/memories/experiences/{knowledgeId}/sources, /skills/{knowledgeId}/sources | memory.listExperienceSources / memory.listSkillSources | memories.read | Associated with the L0 raw evidence layer in Multi-layer memory partitioning |
| Update or forget (delete) an experience/skill | Edit / Forget button at the end of an experience/skill row | PATCH /v1/memory/memories/knowledge/{knowledgeId}, DELETE .../knowledge/{knowledgeId} (or /experiences/{id}, /skills/{id}) | memory.updateKnowledge / memory.forgetKnowledge | memories.write / memories.delete | After forgetting, the status is immediately set to forgotten and online retrieval stops |
Feature Details and Operation Guide
Step One: Submit execution evidence distillation by scope in the Console and retrieve the output
Log in to the Agentbase Console, go to project
企业智能客服与知识中台(enterprise-ai-hub-210) under organizationAgentbase 企业智能中台(69c6d1aa00062e6bb60), click Memory in the left navigation bar, and switch to the Experiences & Skills tab.In the Scope configuration bar at the top, select the target scope:
Scope (
scope): Supportsuser(personal level),agent(agent level;agentIdsuch asenterprise-support-agentmust also be filled in), andproject(project-level global sharing);User ID (
userId): Enteruser_zhangwei_001(oruser_lina_002) and click Apply scope.
In the Manual distillation input area, enter real support ticket troubleshooting conversations and tool return evidence (supports
user:,assistant:, andtool:role identifiers), select Use default Pipeline (or a published custom distillation Pipeline) in the Pipeline dropdown, and click Submit.After submission, you can view the execution status of the distillation jobs (such as
dst_3e5b09f456c5d5c332507ec1dbe3eb6danddst_adc2cfda21c940fb5d5e4a3263ae56f9) (queued -> running -> succeeded) and their output statistics (created,merged,skipped,blocked) in real time in the Distillation task list below.In the Experiences and Skills retrieval area in the lower half of the page, enter a keyword or natural language query (such as
OceanBase 向量内存 -4013orAI 网关 429 限流故障转移) to view the extracted structured experience insights, SOP step details, confidence scores, and source evidence chains.
Step Two: Submit a distillation task containing toolEvents via the REST API and replay to verify
In a real agent runtime, the backend service can submit the full conversation messages together with the structured tool traces toolEvents to POST /v1/memory/memories/distillations after a ticket is closed or a task executes successfully:
export APPBASE_ENDPOINT="https://appbuild.oceanbase.com/v1"
export APPBASE_PROJECT_ID="enterprise-ai-hub-210"
export APPBASE_API_KEY="<APPBASE_API_KEY>"

# 1. Submit a knowledge distillation task with messages and toolEvents (mode="wait", waits up to 20s for the final state)
curl -fsS -X POST "${APPBASE_ENDPOINT}/memory/memories/distillations" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" \
  -H "Idempotency-Key: distill-exp-skill-tk-20261022-001" \
  -H "Content-Type: application/json" \
  --data '{
    "userId": "user_zhangwei_001",
    "agentId": "enterprise-support-agent",
    "scope": "user",
    "sessionId": "sess_ticket_TK_20261022_001",
    "runId": "run_tk_20261022_001",
    "mode": "wait",
    "verifiedSuccess": true,
    "messages": [
      {
        "role": "user",
        "content": "生产告警:enterprise-ai-hub-210 项目在批量构建 1024 维 HNSW 向量索引时报错 OB_ALLOCATE_MEMORY_FAILED (-4013),请排查并恢复。"
      },
      {
        "role": "assistant",
        "content": "已调用 ob_sql_diagnostics 工具核查 GV$OB_VECTOR_MEMORY_INFO,确认租户向量内存池占比仅 10% 且使用率达 98.7%。随后调用 ob_tenant_param_updater 将 ob_vector_memory_limit_percentage 调整为 30%,并重建增量向量索引,验证 schema.status 已恢复为 ready。"
      }
    ],
    "toolEvents": [
      {
        "toolName": "ob_sql_diagnostics",
        "status": "succeeded",
        "durationMs": 42,
        "input": {
          "sql": "SELECT TENANT_ID, USED_VECTOR_MEMORY, LIMIT_VECTOR_MEMORY FROM oceanbase.GV$OB_VECTOR_MEMORY_INFO"
        },
        "output": {
          "tenant_vector_memory_limit_percentage": 10,
          "usage_ratio": 0.987
        }
      },
      {
        "toolName": "ob_tenant_param_updater",
        "status": "succeeded",
        "durationMs": 115,
        "input": {
          "parameter": "ob_vector_memory_limit_percentage",
          "value": 30
        },
        "output": {
          "updated": true,
          "effectiveValue": 30
        }
      }
    ]
  }' | jq .

# 2. Query the details of a specified distillation task and the resulting knowledgeIds
export DISTILLATION_ID="dst_3e5b09f456c5d5c332507ec1dbe3eb6d"
curl -fsS "${APPBASE_ENDPOINT}/memory/memories/distillations/${DISTILLATION_ID}" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" | jq .

# 3. Replay the distillation task when the experience and skill Pipeline has been adjusted or the upstream model has recovered
curl -fsS -X POST "${APPBASE_ENDPOINT}/memory/memories/distillations/${DISTILLATION_ID}/replay" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" \
  -H "Idempotency-Key: replay-dst-3e5b09f4-001" \
  -H "Content-Type: application/json" \
  --data '{}' | jq .
Step Three: Use the Server SDK to retrieve experiences and skills, trace sources, and phase out outdated knowledge
In a Node.js business backend, you can call searchExperiences, searchSkills, listSkillSources, and forgetKnowledge via agentbase-node-sdk@2.10.0 respectively, completing a full closed loop from knowledge retrieval and source auditing to phase-out cleanup:
// Use the official server SDK: agentbase-node-sdk@2.10.0
import { Client, Memory } from 'agentbase-node-sdk';

const client = new Client()
    .setEndpoint('https://appbuild.oceanbase.com/v1')
    .setProject('enterprise-ai-hub-210')
    .setKey(process.env.APPBASE_API_KEY);

const memory = new Memory(client);

// 1. Semantic search for matching troubleshooting experiences (POST /v1/memory/memories/experiences/search)
const experiences = await memory.searchExperiences({
    userId: 'user_zhangwei_001',
    scope: 'user',
    query: 'OceanBase 向量索引构建报 -4013 内存不足如何解决',
    limit: 5
});

for (const exp of experiences.items || []) {
    console.log('[Experience]', exp.knowledgeId, exp.title, '置信度:', exp.confidence);
}

// 2. Semantic search for matching standardized SOP skills (POST /v1/memory/memories/skills/search)
const skills = await memory.searchSkills({
    userId: 'user_zhangwei_001',
    scope: 'user',
    query: '扩容租户向量内存池 ob_vector_memory_limit_percentage 标准步骤',
    limit: 5
});

if (skills.items?.length > 0) {
    const topSkill = skills.items[0];
    console.log('[Skill SOP]', topSkill.knowledgeId, topSkill.name, '步骤数:', topSkill.steps?.length);

    // 3. Trace the L0 raw session and tool trajectory sources supporting that skill (GET .../skills/{knowledgeId}/sources)
    const sources = await memory.listSkillSources({
        knowledgeId: topSkill.knowledgeId,
        limit: 10
    });
    console.log('关联的不可变 L0 Source 数量:', sources.total);
}

// 4. When an old experience is no longer applicable due to a system architecture upgrade, call the forgetting endpoint to immediately stop online retrieval (DELETE)
async function retireObsoleteKnowledge(knowledgeId) {
    await memory.forgetKnowledge({
        knowledgeId,
        userId: 'user_zhangwei_001',
        scope: 'user',
        reason: 'OceanBase 集群已升级至自动弹性向量内存管理,旧手动阈值经验退役'
    });
}
FAQ (Frequently Asked Questions and Troubleshooting)
1. Why can't the skill_extraction and experience_extraction nodes both be disabled when configuring the "Experiences & Skills Pipeline"?
Cause analysis: The core responsibility of the knowledge distillation pipeline (
scenario="distillation") is to produce at least one kind of procedural knowledge from execution evidence. If bothskill_extractionandexperience_extractionare disabled, the entire pipeline degrades into a no-op, so the server-side parameter validator enforces that at least one of the two must be enabled. When you disable one of them (for example, enabling onlyexperience_extractionwhile disablingskill_extraction), its associated merge node (skill_merge) is automatically skipped at runtime, but the original configuration parameters are still safely retained in the draft.Solution: Keep at least one extraction node enabled according to business needs; after saving the draft, click Dry-run to verify the extraction results, then click Publish.
2. When submitting a distillation request with mode: "wait", if an HTTP 202 with "waitTimedOut": true is returned, has the task failed? Does it need to be resubmitted?
Root Cause: The task has not failed and absolutely does not need to be resubmitted.
mode: "wait"indicates that the gateway layer blocked and waited on behalf of the client for at most 20 seconds; when the input conversation and tool traces are long, or when the seven-step pipeline sequentially invokesqwen-plusto perform skill extraction, skill merging, experience extraction, experience merging, and quality validation taking longer than 20 seconds, the server safely ends that HTTP synchronous wait, returns HTTP202 Acceptedalong withwaitTimedOut: true, while the distillation task in the background Worker continues to execute normally.Resolution: Read the
distillationIdfrom the response directly, and poll viaGET /v1/memory/memories/distillations/{distillationId}until the status enterssucceeded; even if the sameIdempotency-Keyis mistakenly retried, the idempotency guard will safely return the same distillation task without charging for duplicate execution.
3. Why does activating or approving an experience (Experience) that has already completed extraction prompt skill_dependency_not_approved?
Root Cause: In the seven-step distillation pipeline, the troubleshooting experiences extracted in Step 4 (
experience_extraction) automatically establish dependency references to relatedSkillproduced in the same batch by Step 2/3 (skill_extraction/skill_merge). If the project has enabled secondary confirmation (evolution.requireConfirmation: true) or theSkillis still in theshadow(pending confirmation/not activated) state, to prevent retrieved experiences in production from pointing to an SOP skill that is not yet effective or not yet approved, the system blocks the standalone activation of that experience through theskill_dependency_not_approvedgate.Resolution: Go to the memory → experiences and skills → versions and confirmations sub-tab (see experience and skill evolution and manual confirmation governance); first review and approve the dependent
Skillcandidate version to bring it into theactivestate, then approve the correspondingExperience.