
Evaluation Dataset Management and Benchmark Testing
Feature Overview
Evaluation Datasets (Console entry: Agent Ops → Datasets) are Agentbase's (v2.10.0) core data asset center supporting offline regression testing of agents, Prompt version comparison, model selection evaluation, and continuous accumulation of online Bad Cases. During enterprise-grade AI application iteration, whenever a team upgrades the underlying large model (for example, switching from qwen-turbo to qwen-plus), adjusts system prompts, or modifies the knowledge base kb_enterprise_support retrieval threshold, a Golden Dataset containing standard inputs (input) and reference standard answers (expectedOutput) is needed to scientifically verify whether the change truly improves accuracy without causing regression of historical cases.
In the example project 企业智能客服与知识中台 (enterprise-ai-hub-210) under Agentbase 企业智能中台 (69c6d1aa00062e6bb60), the team maintains the core golden evaluation set enterprise-support-golden-v1 (covering four major domains represented by tickets TK-20261022-001 through 004: OceanBase distributed transaction troubleshooting, HNSW vector index tuning, AI gateway rate-limiting and billing, and standard customer service SOPs), achieving a complete closed loop from “production pipeline collection → dataset item management → automated benchmark run (Agent Runtime Workbench or remote custom endpoint) → multi-turn evaluation scoring and root cause comparison.”
Core Concepts and Architecture
The dataset engine binds static test items (Dataset Items) with dynamic execution trajectories (Traces / Observations) into immutable run records (Dataset Runs), and seamlessly integrates with automated evaluators (Evaluations) to build a repeatable, comparable benchmark evaluation pipeline.
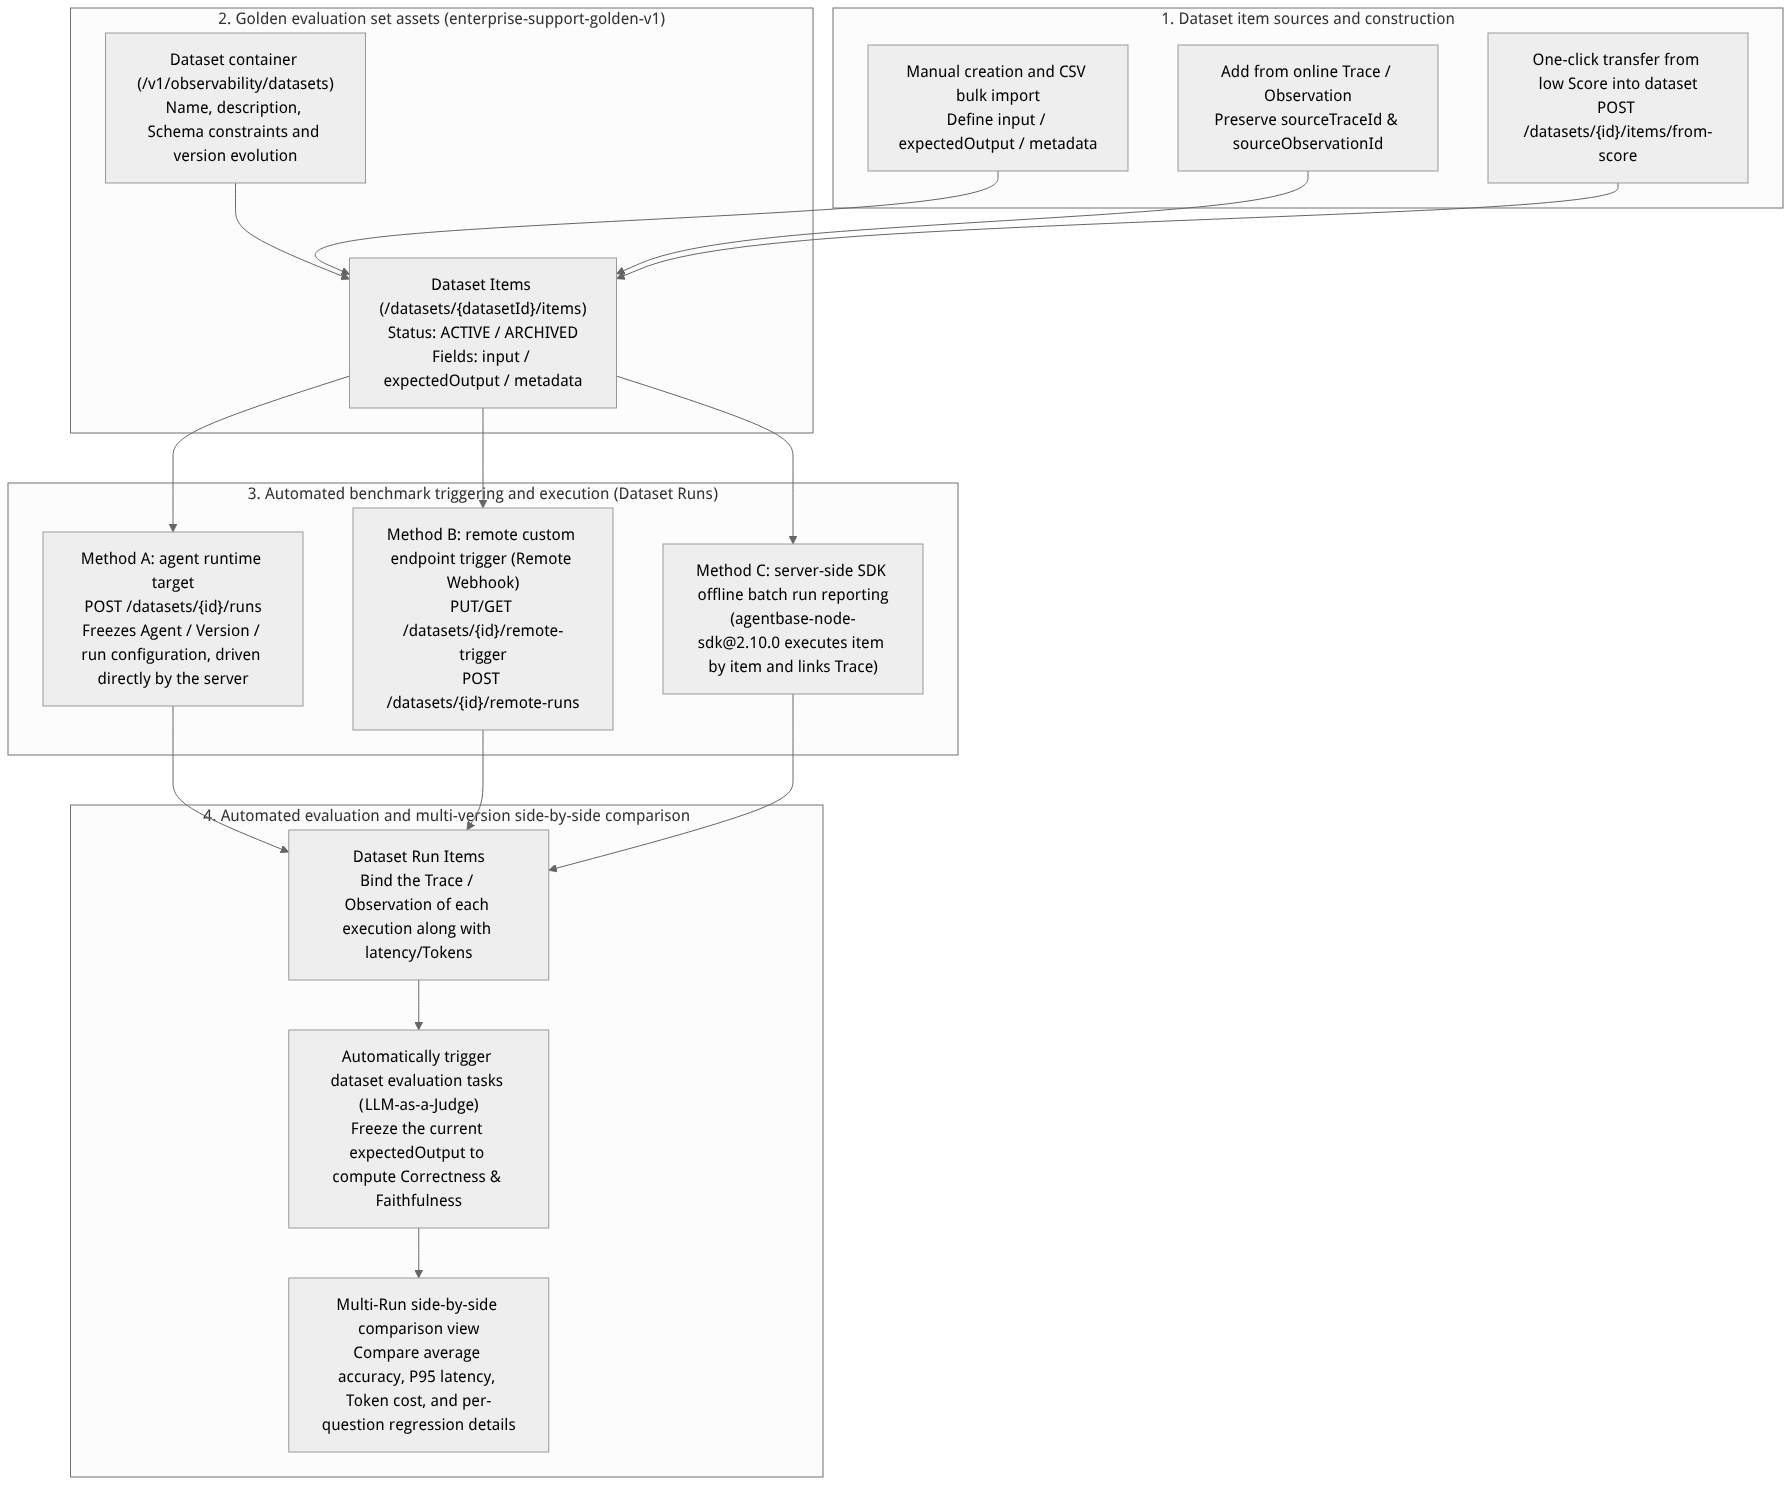
Flow diagram, not a runtime screenshot; read the relationships between steps or states along the arrows.
View the flow diagram in full size
Dataset Core Entities and Field Definition Table
| Core entity | Key fields | Type and constraints | Business meaning and evaluation role |
|---|---|---|---|
| Dataset | namedescriptionmetadatainputSchemaexpectedOutputSchema | string (required, unique within the project, e.g., enterprise-support-golden-v1)string / objectoptional JSON Schema | A logical container organizing similar evaluation cases. Supports optional configuration of inputSchema and expectedOutputSchema to perform structured JSON Schema validation on new items. |
| Dataset Item | idinputexpectedOutputmetadatasourceTraceIdsourceObservationIdstatus | input: required (JSON or text)expectedOutput: optional standard answerstatus: ACTIVE (default) or ARCHIVED | A single benchmark test question. When status is set to ARCHIVED, the item retains its historical associated records but no longer participates in subsequently created benchmark runs (Dataset Runs). |
| Dataset Run | runId / namedescriptionmetadata | Binds to a specific test configuration snapshot (e.g., qwen-plus-v1 vs qwen-turbo-v1) | A complete regression test batch initiated against the same dataset. When targeting Agent Runtime, the Agent version, model parameters, and knowledge base configuration at that time are automatically frozen. |
| Dataset Run Item | datasetItemIdtraceIdobservationId | Links a single question with the Trace / Observation actually generated in that run | Precisely anchors the static question (including expectedOutput) with the dynamic inference results of that run (output, latency, tokens, cost) and the Score produced by automated evaluation. |
Roles, Entry Points, and Relationships
Console Entry and REST API Permission Matrix
The Console entry is located at: Project enterprise-ai-hub-210 → Agent Ops (Observability / AgentOps) → Datasets (route: /console/project-{region}-enterprise-ai-hub-210/datasets).
| Operation | Console entry | REST API endpoint | Required permission Scope |
|---|---|---|---|
| Query and create datasets | Dataset list page → Create dataset | GET/POST /v1/observability/datasets, GET .../:datasetId | observability.datasets.read / write |
| Manage dataset items and CSV import | Dataset detail → Items tab / Import CSV | GET/POST /v1/observability/datasets/:datasetId/items, PATCH/DELETE .../:itemId | observability.datasets.read / write |
| Batch-transfer low Scores into a dataset | Score list/detail → Add to dataset | POST /v1/observability/datasets/:datasetId/items/from-score/preview, /from-score | observability.datasets.write + scores.read |
| Trigger dataset runs (including Agent Workbench target) | Dataset detail → Runs → New run | GET/POST /v1/observability/datasets/:datasetId/runs, GET .../runs/:runId/items | observability.datasets.write |
| Configure and trigger remote custom endpoint runs | Dataset detail → Remote Trigger configuration | GET/PUT/DELETE /v1/observability/datasets/:datasetId/remote-trigger, POST .../remote-runs | observability.datasets.write |
Synergy with Other Modules
Bidirectional backflow with Traces and Scores: When a typical online Bad Case is discovered during operations (e.g., a ticket Q&A exhibiting hallucination or retrieval omission), operators can click Add to dataset directly on the Trace, Observation, or low Score page to capture the real online input (
input), model output, andsourceTraceId/sourceObservationIdintoenterprise-support-golden-v1with one click, preventing similar issues from recurring in subsequent iterations.Signature-freeze linkage with Evaluations and root cause analysis (RCA): Only runs bound to dataset standard answers (
expectedOutput) can enable the Answer accuracy (Accuracy / Correctness) evaluation in the four-stage RAG evaluation. During evaluation execution, the system uses an independent-domain HMAC signature to freeze the current question, reference answer (expectedOutput), Trace, and RAG retrieval fingerprint indatasetEvidence— afterwards, even if someone modifies the current standard answer of a dataset item, the root cause analysis (RCA) of historical scores still strictly verifies the frozen snapshot from that run, avoiding incorrect attribution.
Feature Details and Operation Guide
1. Create the golden dataset enterprise-support-golden-v1 and enter items
Log in to the Agentbase Console, enter project
企业智能客服与知识中台(enterprise-ai-hub-210), and open Agent Ops → Datasets.Click Create dataset in the upper-right corner, fill in the name
enterprise-support-golden-v1and description"企业智能客服与技术支持黄金基准集(覆盖 OceanBase 排障、AI 网关限流与 SOP 问答)", and click Save.Three ways to enter dataset items:
Method One: manual creation or CSV batch import: On the dataset detail page, click New item or Import CSV, and batch import a table containing
input(user ticket question),expectedOutput(standard troubleshooting steps and answer), andmetadata(e.g.,{"ticketCategory": "oceanbase-vector", "difficulty": "hard"});Method Two: convert from online Traces / Observations: On the Agent Ops → Traces detail page, select a typical trace or
GENERATIONnode, click Add to dataset, chooseenterprise-support-golden-v1, polish and correctexpectedOutputmanually, and save; the system automatically recordssourceTraceIdandsourceObservationId;Method Three: batch conversion from low Scores (
from-score): Filter low-score records on the scores page, first call/items/from-score/previewto preview the deduplication status, then call/items/from-scoreto batch-transfer them into the dataset.
export APPBASE_ENDPOINT="https://appbuild.oceanbase.com/v1"
export APPBASE_PROJECT_ID="enterprise-ai-hub-210"
export APPBASE_API_KEY="<APPBASE_API_KEY>"

# 1. Create the golden evaluation dataset enterprise-support-golden-v1
DS_RESP="$(curl -fsS -X POST "${APPBASE_ENDPOINT}/observability/datasets" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" \
  -H "Content-Type: application/json" \
  --data '{
    "dataset": {
      "name": "enterprise-support-golden-v1",
      "description": "企业智能客服与知识中台黄金评测基准集 (v2.10.0)",
      "metadata": {
        "owner": "enterprise-ai-hub-team",
        "knowledgeBaseId": "kb_enterprise_support"
      }
    }
  }')"

DATASET_ID="$(echo "${DS_RESP}" | jq -er '.dataset.id')"

# 2. Add golden evaluation entries linked to online ticket Traces to the dataset
curl -fsS -X POST "${APPBASE_ENDPOINT}/observability/datasets/${DATASET_ID}/items" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" \
  -H "Content-Type: application/json" \
  --data '{
    "item": {
      "input": {
        "question": "OceanBase Shared V2 项目在构建 1024 维 HNSW 向量索引时报错 -4013 (OB_ALLOCATE_MEMORY_FAILED),应该如何排查和修复?",
        "userId": "user_zhangwei_001"
      },
      "expectedOutput": {
        "answer": "1. 查询 GV$OB_VECTOR_MEMORY_INFO 核实租户向量内存使用率;2. 调大租户参数 ob_vector_memory_limit_percentage(建议从默认 10% 提升至 30%);3. 重新触发增量向量索引构建并确认 schema.status=ready。",
        "mustIncludeSql": "GV$OB_VECTOR_MEMORY_INFO"
      },
      "metadata": {
        "ticketId": "TK-20261022-001",
        "domain": "oceanbase-vector-index",
        "sla": "P0"
      },
      "sourceTraceId": "tr_support_ticket_20261022_001",
      "sourceObservationId": "obs_gen_qwen_plus_001"
    }
  }' | jq .
2. Trigger automated benchmark testing (Agent Runtime Workbench vs custom remote endpoint vs SDK)
Once the dataset enterprise-support-golden-v1 is ready, automated benchmark runs (Dataset Runs) can be initiated in the following three modes:
| Run mode | Trigger entry / interface | Execution principle and core advantages | Applicable scenarios |
|---|---|---|---|
| Mode A: Agent Runtime Workbench target | Console Datasets → New run → Select Agent Runtime (POST /v1/observability/datasets/:datasetId/runs) | The browser does not connect directly to the underlying Runtime service; the platform server automatically iterates over all ACTIVE items in the dataset, initiates real ReAct runs against the current project's Agent Workbench, automatically freezes the Agent version, model (qwen-plus), knowledge base (kb_enterprise_support), and lexicon configuration at that time, and automatically attaches the generated Traces as Dataset Run Items. | Evaluating the effect comparison of different configuration versions of customer service agents hosted on the Agentbase Agent Workbench. |
| Mode B: custom remote endpoint (Remote Webhook) | Console Configure remote trigger (PUT .../remote-trigger) and click Trigger remote run (POST .../remote-runs) | After registering the HTTPS Webhook address and authentication headers of the business's self-built Agent service, the platform pushes dataset items in batches to the custom endpoint for execution, and associates the returned responses and Traces back to the current Run. | Business agents deployed in self-built microservices or Functions, where the team wants to trigger regression testing with one click from the Console. |
| Mode C: Programmatic batch runs via server-side SDK | Use agentbase-node-sdk@2.10.0 in CI/CD pipelines to pull items, invoke models, and report associated | . Gain fully autonomous control over concurrency, prerequisite data preparation, and multi-step orchestration in local or CI scripts, and record comparison batches via POST /v1/observability/datasets/:datasetId/runs. | Automated quality gates integrated into Git commits or daily scheduled builds (Nightly Build). |
Example of triggering an Agent Runtime Workbench automated benchmark run
# Trigger a benchmark run against the Agent Runtime workbench for enterprise-support-golden-v1
curl -fsS -X POST "${APPBASE_ENDPOINT}/observability/datasets/${DATASET_ID}/runs" \
  -H "X-Appwrite-Project: ${APPBASE_PROJECT_ID}" \
  -H "X-Appwrite-Key: ${APPBASE_API_KEY}" \
  -H "Content-Type: application/json" \
  --data '{
    "run": {
      "name": "benchmark-qwen-plus-graphrag-v210",
      "description": "启用 kb_enterprise_support GraphRAG + Wiki 及 lex_enterprise_synonyms 词典后的基准回归",
      "target": {
        "type": "agent_runtime",
        "agentId": "enterprise-support-agent"
      },
      "metadata": {
        "model": "qwen-plus",
        "knowledgeBase": "kb_enterprise_support",
        "releaseBaseline": "2.10.0"
      }
    }
  }' | jq .
3. Compare multiple versions side by side in the Runs view and drill down into per-item regressions
Go to the Runs tab of dataset
enterprise-support-golden-v1.Select two or more different run batches (for example
benchmark-qwen-turbo-baselineandbenchmark-qwen-plus-graphrag-v210) to enter the side-by-side comparison view:Global aggregate metrics comparison: intuitively compare each batch's average score, P50/P95 response latency, average Token consumption, and estimated total cost per run across evaluators such as Correctness, Faithfulness, and Context Relevance;
Item-by-item drill-down comparison: the table displays row by row the same
datasetItem's actual output (Output), score differences, and status across different Runs. For degraded cases with lower scores, click the associated Trace link to go directly to Trace details and root cause analysis to locate the cause.
Entry point and creation
Open Observability / AgentOps in the project sidebar and go to Assets / Data → Datasets. If you do not see this section, first confirm that observability is enabled on the current instance; see Observability overview.
Click Create dataset and fill in the name; description and metadata are optional.
Select the case type: Default, Good, or Bad. Use a JSON object format when metadata needs to be filled in.
After saving, you will enter the dataset detail page, where you can maintain test cases in Items, view run records in Runs, and compare run results in Reports.
Adding test cases
Each case requires an input and an expected output. You can create them manually or import a CSV. When editing a case, you can also associate an existing Trace and select Observations from it as needed, making it easy to build regression samples from real requests.
Importing from CSV
Select Import CSV to upload a UTF-8 .csv file with headers. First check the column mapping and preview, then start the import. At least one column must be mapped to Input and one to Expected output; remaining columns can be mapped to Metadata or ignored. Common headers are matched automatically, but you should still confirm them in the preview:
| CSV header example | Default mapping |
|---|---|
input、question、query、prompt | Input |
expected_output、ground_truth、reference_answer | Expected output |
metadata、meta | Metadata |
| Other columns | Ignored |
For example, the following two-column CSV directly satisfies the required mappings:
input,expected_output
"如何重置密码?","在登录页选择忘记密码,并按页面提示完成操作。"
A single file can be at most 10 MiB, with at most 1,000 data rows and 100 columns. If the file is empty, has empty or duplicate headers, is malformed, or exceeds the limits, fix the CSV before uploading again. If individual data rows fail to write, the import result keeps the success/failure counts along with failed row numbers and reasons; before retrying, filter out the failed rows first — reimporting the entire file may duplicate already-successful records. Do not assume all records succeeded merely because the import "completed".
Building cases from Traces
In the source selector when adding or editing an item, search for and select a Trace; if you need to locate a specific step, select an Observation within that Trace. After saving, the item retains its source association, and you can return from the case to the corresponding trace to inspect context. If you switch the Trace, you need to re-confirm the Observation selection.
Running and viewing results
Create a Run on the dataset detail page, fill in the run name, and choose an execution mode:
| Execution mode | Pre-run checks |
|---|---|
| Prompt | First select the evaluation template, Prompt/version, and LLM connection, then fill in the model and model parameters JSON; the page will prompt for any missing required configuration. |
| Agent | Select the project Draft Agent or an external Agent target on the AI Gateway; if the list is empty, first confirm that an available target exists in the project. |
After the run, check status and records in Runs. Open an individual run's details to compare input, expected output, actual output, and scores item by item; the page also shows available Traces, latency, cost, and failure information. Reports lets you compare average latency, average cost, and scores across different Runs. If a run or scoring is still processing, a score is empty, or a case failed, first check the corresponding status, errors, and Traces; an empty score does not mean a score of zero, nor does it mean the case passed.
Dataset runs depend on Prompts, model connections, or Agent execution targets available in the current project, as well as configured evaluators. For evaluation configuration and result interpretation, see Evaluations and scoring; for metric sources and trace-derived signals, see Metrics analysis.
When testing knowledge base Q&A, keep the questions and reference answers fixed, select an Agent that produces genuine retrieval evidence, and combine query quality, context relevance, answer faithfulness, and answer accuracy templates. For the complete procedure and submission exception handling, see Evaluating RAG answers with datasets. Actual answers cannot replace reference answers, and missing scores cannot be used as evidence of passing.
FAQ and Troubleshooting
1. When selecting the "Answer Accuracy (Accuracy / Correctness)" template in dataset evaluations, why do some items produce no score?
Cause analysis: Answer Accuracy (Correctness) evaluation strongly depends on the dataset item containing a non-empty valid reference standard answer (
expectedOutput). If a Dataset Item only hadinputfilled in when created or imported from a Trace, whileexpectedOutputwas empty or missing, the evaluation engine will refuse to submit an empty standard answer to the Judge model, and thus skips accuracy scoring for that item.Resolution: Check the items that produced no score in the dataset's Items tab, fill in a complete
expectedOutputstandard answer, and then trigger a new Dataset Run.
2. After modifying an item's expectedOutput standard answer, will the scores and root cause analysis of previously completed historical Dataset Runs change automatically?
Cause analysis: No. To guarantee the reproducibility and audit rigor of historical experiment conclusions, Agentbase takes a signed snapshot freeze of the
inputandexpectedOutputat the time of every dataset evaluation execution (saved in thedatasetEvidencemetadata of the Score). Subsequent modifications to dataset items only take effect for newly initiated Dataset Runs.Resolution: After correcting the standard answer, create a new Dataset Run to obtain evaluation scores and root cause analysis based on the latest standard answer.
3. How can I temporarily mask old items in a dataset that are no longer applicable, while keeping their comparison records in historical Runs?
Cause analysis: Physically deleting (
DELETE) a Dataset Item directly would cause historical Runs to lack the item's stem for comparison.Resolution: Do not delete the item directly; instead, edit it (
PATCH /v1/observability/datasets/:datasetId/items/:itemId) to switch its status fromACTIVEtoARCHIVED(archived). Archived items will not enter subsequently triggered benchmark runs, but they remain fully preserved and viewable on the historical Run detail pages.