
GraphRAG, RAPTOR, and Advanced Knowledge Index Build Governance
Knowledge indexes add GraphRAG graphs, RAPTOR summaries, and Wiki pages to basic retrieval. Configure, build, and inspect them on the knowledge base Knowledge Index page; model and capability availability depend on the deployment.
Feature overview and core scenarios
Knowledge indexes produce derived results from existing documents and chunks: GraphRAG helps explore entities and relationships, RAPTOR builds layered summaries, and Wiki organizes readable knowledge pages. Before choosing a capability, check deployment support, model configuration, and source document status; verify generated results against their sources.
Core Concepts and Architecture
GraphRAG build flow
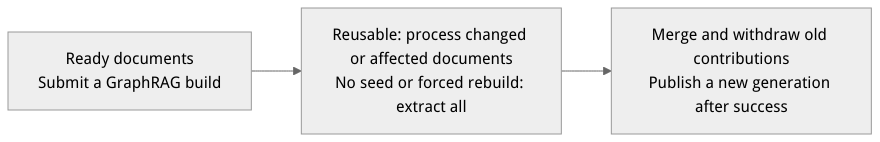
Flow diagram, not a runtime screenshot; read the relationships between steps or states along the arrows.
View the flow diagram in full size
One. GraphRAG
GraphRAG extracts entities and relationships from document chunks and can apply entity resolution and community analysis when configured. Use it to explore cross-document relationships, and verify results against the source material.
| Configuration | Description |
|---|---|
enabled | Enables this capability; defaults to false. |
entityTypes | Entity types; system defaults apply when omitted. |
method | Extraction method: light or general; defaults to light. |
resolution / community | Enables entity resolution / community analysis; both default to false. |
lexiconEnabled | Uses bound lexicons during graph construction; defaults to false. |
maxEntitiesPerUnit | Optional entity budget per extraction unit, JSON integer 1–128. |
language | Output language: auto, zh, en, or ja; defaults to auto. |
Two. RAPTOR summary index
RAPTOR clusters and summarizes chunks into layered semantic results. It uses configured models rather than a fixed provider or vector dimension.
| Configuration | Description |
|---|---|
enabled | Enables this capability; defaults to false. |
scope | document builds per document, knowledgeBase builds per knowledge base; defaults to document. |
prompt | Summary prompt. |
maxToken | Summary token limit; defaults to 256, range 1–2048. |
maxCluster | Maximum cluster count; defaults to 64, range 1–1024. |
threshold | Cluster threshold; defaults to 0.1, range 0–1. |
language | Output language: auto, zh, en, or ja. |
Three. Wiki compilation
Wiki can generate pages from configured sources. When automatic compilation is enabled and configured to wait for the graph, await_graphrag may appear; inspect the GraphRAG and Wiki jobs. Page count and duration depend on the actual sources and settings. Automatic compilation options include autoCompileOnDocumentUpdate, autoCompileSources, and autoCompileWaitForGraphRag; Wiki build concurrency uses wikiPageMaxConcurrent.
Four. Dual-Axis State Machine, Staleness Reasons (staleReason), and ModelCapacity Capacity Governance
1. Capability state and result generation
The response exposes available, configured, and enabled to indicate deployment availability, saved configuration, and enablement. state describes the current index state. activeResultGeneration identifies the published result and is not an integer to increment directly. Build jobs have their own status; acceptance alone does not mean completion.
2. Common staleness reasons (staleReason)
| Reason | Meaning |
|---|---|
document_generation_changed | A document ingestion generation changed |
document_deleted | A document was deleted |
document_enabled_changed | A document's enabled state changed |
document_metadata_changed | Document metadata changed |
chunk_changed | A chunk changed |
indexing_model_changed | The indexing model changed |
document_processing_config_changed | Document processing configuration changed |
capability_config_changed | Capability configuration changed |
When a capability is stale, inspect the change and capability state, then start a build as appropriate and wait for the job result. Whether an older result can be used depends on the retrieval path and state; successful retrieval is not guaranteed.
3. Model call capacity
Within an indexer process, separate limits apply to concurrent chat and embedding model calls. Capabilities and jobs share the corresponding capacity. Throughput also depends on model services and deployment settings; these limits do not guarantee online retrieval latency or model quota.
Feature Entrypoints and Permission Matrix
| Console entrypoint / feature module | Frontend route path | Corresponding REST API endpoint | Server SDK method (Node.js / Python) | Required RBAC role / API Key scope | Cross-module dependency |
|---|---|---|---|---|---|
| Knowledge base → Knowledge index overview page | /console/project-default-enterprise-ai-hub-210/knowledge-base/kb-kb_enterprise_support/indexes | GET /v1/knowledgebases/{kbId}/index-capabilities | knowledgeBase.listIndexCapabilities() / list_index_capabilities() | Roles: owner, admin, developer, member (read-only)Scope: knowledgebases.read | Capability and build prerequisites depend on the environment |
| Configure GraphRAG / RAPTOR / Wiki capability parameters | /console/.../kb-kb_enterprise_support/indexes (click "Configure" on the corresponding card) | PATCH /v1/knowledgebases/{kbId}/index-capabilities/{capability} | knowledgeBase.updateIndexCapability() | Roles: owner, admin, developerScope: knowledgebases.write | Configure models required by the selected capability; check bindings when enabling lexiconEnabled |
| Dispatch incremental build, repair, or full rebuild jobs | /console/.../kb-kb_enterprise_support/indexes (click "Build" or "Rebuild") | POST /v1/knowledgebases/{kbId}/index-operationsGET /v1/knowledgebases/{kbId}/index-operations | knowledgeBase.createIndexOperation()knowledgeBase.listIndexOperations() | Roles: owner, admin, developerScope: GET knowledgebases.read; POST knowledgebases.write | Linked with the ready gating of version management (Versions) |
| Cancel a running index job | Row action "Cancel" in the recent jobs list | POST /v1/knowledgebases/{kbId}/index-operations/{operationId}/cancel | knowledgeBase.cancelIndexOperation() | Roles: owner, admin, developerScope: knowledgebases.write | Only takes effect on jobs in queued or running status |
| Clear derived index data | Capability card more menu "Clear Index Data (Clear)" | POST /v1/knowledgebases/{kbId}/index-capabilities/{capability}/clear | knowledgeBase.clearIndexCapability() | Roles: owner, adminScope: knowledgebases.write | The request body must provide confirmation and idempotencyKey; only derived indexes are cleared, without deleting original documents and base chunks |
Feature Details and Operation Guide
Step 1: Configure index capabilities
Open the project and target knowledge base, then open Knowledge Index. Availability depends on the deployment and project configuration.
Choose GraphRAG, RAPTOR, or Wiki as needed, open its configuration, enable the capability, and fill in the required options. Configure available models for the capability before building; if using lexicon enhancement, check the knowledge base bindings first.
After saving, check the configuration and capability state before submitting a build. Select language, models, and documents for your environment; the page does not prepopulate the example data in this guide.
Step 2: Build an index and inspect the job
Select the capability to build on the knowledge index page and submit the build, then inspect the corresponding job status. The REST API uses kind to select build or repair; a 202 response only means the request was accepted.
An ordinary GraphRAG build can reuse a previous successful result when eligible; without a usable seed or after incompatible configuration changes it falls back to full processing. Deleting or changing shared content may also require re-extracting related documents, so time and model consumption depend on the job. To force re-extraction for a GraphRAG job, set config.forceRebuild to true; this differs from force, which cancels another active job.
Step 3: Fully operate the three index capabilities and job lifecycles via the REST API
The write examples below target a knowledge base with versioning enabled: replace <DRAFT_VERSION_ID> with the target draft version ID. For a knowledge base without versioning, omit versionId from the requests. The configuration examples below are for new configurations: PATCH replaces the entire config. Before changing existing settings, retrieve them and merge the fields to keep. Clearing removes the selected derived result; verify the target before proceeding.
Query the current status, generation number and staleness reason of the knowledge base's three advanced index capabilities (GET /index-capabilities)
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X GET "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-capabilities?versionId=<DRAFT_VERSION_ID>" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @-
)
Example: configure GraphRAG (PATCH replaces the complete config)
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X PATCH "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-capabilities/graphrag" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{
    "versionId": "<DRAFT_VERSION_ID>",
    "config": {
      "enabled": true,
      "language": "zh"
    }
  }'
)
Example: configure RAPTOR (PATCH replaces the complete config)
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X PATCH "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-capabilities/raptor" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{
    "versionId": "<DRAFT_VERSION_ID>",
    "config": {
      "enabled": true,
      "language": "zh"
    }
  }'
)
Example: configure Wiki (PATCH replaces the complete config)
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X PATCH "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-capabilities/wiki" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{
    "versionId": "<DRAFT_VERSION_ID>",
    "config": {
      "enabled": true,
      "language": "zh"
    }
  }'
)
Submit a GraphRAG build job (POST /index-operations)
Generate a new, unique idempotencyKey for each independent build and replace the placeholder; reuse the original key only when retrying the same request. Reusing an old key may return the existing job without rebuilding. After submission, query the job until it reaches a terminal state.
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X POST "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-operations" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{
    "versionId": "<DRAFT_VERSION_ID>",
    "capability": "graphrag",
    "kind": "build",
    "config": {"forceRebuild": false},
    "idempotencyKey": "<NEW_BUILD_OPERATION_KEY>"
  }'
)
Cancel a queued or running build job (POST /index-operations/{operationId}/cancel)
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X POST "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-operations/iop_7c6b5a4d3e2f1098/cancel" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{"versionId":"<DRAFT_VERSION_ID>"}'
)
Clear the RAPTOR derived index after checking the target. Run separately only after confirming the target and consequences. Use a new, unique
idempotencyKeyfor each independent cleanup; reuse the original key only when retrying the same request, or an old cleanup job may be returned. After submission, query the job until it reaches a terminal state.
(
  set +x
  set -o pipefail
  : "${APPBASE_API_KEY:?Set APPBASE_API_KEY}"
builtin printf 'X-Appwrite-Key: %s\n' "$APPBASE_API_KEY" | curl --disable -X POST "https://<your-endpoint>/v1/knowledgebases/<KNOWLEDGE_BASE_ID>/index-capabilities/raptor/clear" \
  -H "X-Appwrite-Project: <YOUR_PROJECT_ID>" \
  --header @- \
  -H "Content-Type: application/json" \
  -d '{
    "versionId": "<DRAFT_VERSION_ID>",
    "confirmation": "clear:raptor",
    "idempotencyKey": "<NEW_CLEAR_OPERATION_KEY>"
  }'
)
FAQ (Frequently Asked Questions and Troubleshooting)
Q1: Why is an index stale after a document update?
Changes to documents, chunks, models, or capability configuration can make a published result stale. Check staleReason and the job status, then rebuild the affected capability. Document ingestion success does not mean the index build succeeded; do not assume an older result can serve every retrieval path.
Q2: Why is Wiki waiting for GraphRAG?
If Wiki depends on GraphRAG and its graph result is not ready, it may show await_graphrag. Inspect the configured sources and both job statuses, and investigate any reported error. Completion time depends on the job and environment.
Q3: How do I update the graph after changing a lexicon?
A build with lexiconEnabled uses the lexicon configuration at build time. Changing the lexicon does not rewrite existing results automatically. Rebuild GraphRAG when needed and verify the new result.
Q4: Does clearing a derived index delete source documents?
Clearing targets the selected capability's derived index, not source documents or base chunks. Verify the capability and environment first; the REST request needs confirmation (for example, clear:raptor) and idempotencyKey. Rebuild the capability after clearing if it is needed again.
Related Documentation
External data source integration and incremental sync with Yuque
Knowledge Graph Visualization Exploration and Community Reports
Knowledge Base Wiki Compilation, Conflict Adjudication, and Memory Export
Knowledge Base Immutable Version Management and Release Rollback
Project-level lexicons and retrieval/knowledge graph/agent collaborative governance
Knowledge Base Settings Hub, Default Policies, and Multimodal Image Understanding (VLM)
Scenario directories and enhancement operations
Open Knowledge Base → Scenario library from the project sidebar to organize support scenarios such as refunds, shipping and account issues in a category tree. Each scenario stores a name, full category path and definition. Create categories and scenarios, or parse an Excel/CSV file first, inspect column mappings, the directory tree, conflicts and import candidates, and then confirm the import. Parsing and previewing do not mean that records have been saved. Return to the category tree to check names, definitions and counts. Scenario read/write permissions are required; knowledge bindings also require permission on the relevant knowledge base.
In GraphRAG scenario mode, select a category or select scenarios using pagination before starting a build. Scenario names, full category paths and definitions become entities; associated documents supply descriptions and relationships. The supplementary entity description prompt has a different purpose from the previous description summary prompt. Rebuild existing graphs to apply new settings. Check category bindings, terminal build state and entity evidence; selecting a scenario alone does not update the graph. Wiki can aggregate by scenario directory.
After chunking, rerun keyword, question and metadata enhancement against stored chunks. Clearing removes enhancement results. Select the entire knowledge base or specific documents. One shot configuration only affects that operation and does not overwrite knowledge base settings. Filling only missing results can reduce duplicate model calls. Inspect progress and failure details before retrying; cancellation does not erase work already completed.